Episode 2. I Burn a Whole Day on One Scroll, and Still Keep Going
The last episode ended with the fact that "the AIs did not know which models they were." Let us start there.
AI Does Not Know Itself
Whenever I asked, they kept giving me names from several generations ago. Did GPT and Claude give me the right answer after I told them to look again and get it right?
No. At least GPT and Claude displayed their model names, so I think I told them what they were and they replied, "Oh, right."
Gemini did not even have proper model names at the time. Today you see names like "3.5 Flash," but back then I think it was just something like fast, medium, and pro. Google Studio let me select a model when running a task, so I looked at the list and told Gemini which models it was using.
This problem kept coming back. For example, if I told Gemini about GPT 5.4 mini, it would say no such model existed. I would answer, "No, I am right. Just move on."
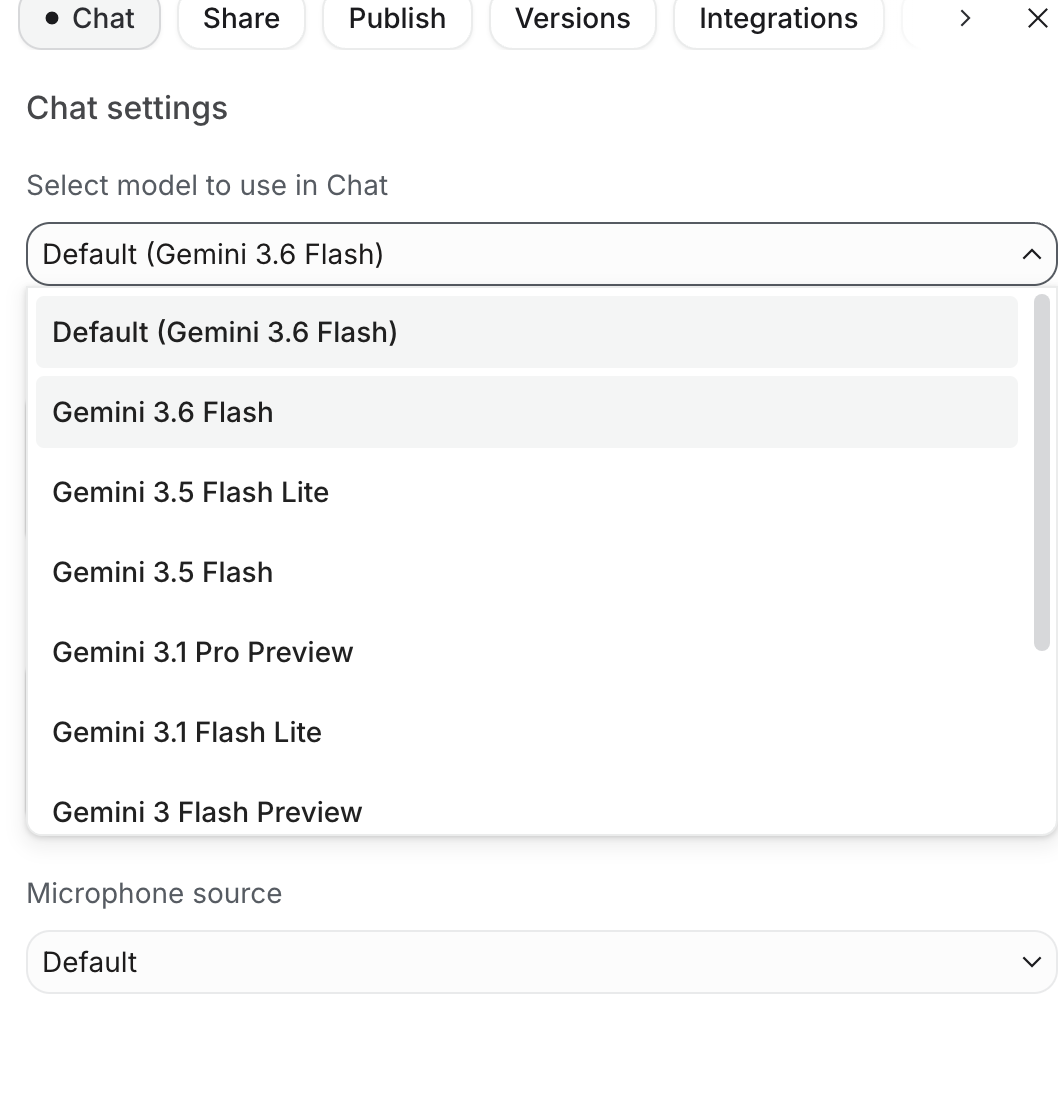
<Image 2-1. Model selection list>
The Bigger Shock — The APIs Could Not Search the Web
Did everyone else know that AIs like Claude and GPT do not always search the web?
If you look through each service's settings, there is a toggle that allows web search.
I genuinely did not know this. I assumed the AIs always searched the internet before answering.
But the API versions you connect to an app could not search the web. They knew nothing about the world after the cutoff point of their training data.
Ask about something after 2023 or 2024 and they would spout complete nonsense.
I discovered this by asking for the audience count of the movie The Man Who Lives with the King. It replied, "Do you mean The King and the Clown?" and started making things up.
If I asked for the name of the male actor in Netflix's Lady Dua, it would make things up again.
I asked whether even one of the three could search the web, and one claimed it could. Then I asked for today's Samsung Electronics stock price, and it gave me the price from 2024.
That meant I had to add web search myself, which was another difficult job.
And the same problem appeared again: the AIs did not really know how their own web search worked.
I had to tell each of them over and over: check carefully, check again, read the official documentation. Only then did I get it working.
Was it Gemini again? I think one of them kept talking nonsense until the very end.
It took at least half a day.
An Entire Day Lost to One Scroll
Even now, this feels ridiculous.
What I wanted was simple. When I sent a message, my message bubble would move neatly to the top of the screen, and the AI's answer would flow down beneath it. Every chatbot works like that. Just that natural scrolling behavior.
I spent an entire day on it.
My message would not stick to the top, so I added spacing. Then the scroll would stutter while the answer appeared, so I changed it again. Fix one thing and something else broke.
I could not understand why such a small behavior was so difficult.
The funnier part is that later, when I built Omni Brain—the next version—I lost another whole day to exactly the same problem.
The same scrolling issue. I still do not understand why it was so hard.
I can barely remember whether I ever got it working properly in Omni LLM. That is how sick of it I became.
Reordering Tabs — An Endless Screenshot Hell
I also added a feature for dragging the tabs at the top to change their order.
Grab a tab, drag it sideways, and the tabs switch places. That feature.
Even this took a long time. Was it not one of the most basic interactions? It feels completely natural in something like Chrome.
Whenever it failed, I took a screenshot and showed the AI: "This is what it looks like. What is wrong?" It would fix something, it still would not work, and I would take another screenshot. I have no idea how many screenshots I took.
It Worked on My Phone, So I Kept Adding Things
Google AI Studio also worked on a phone, so I kept adding all the features I wanted.
I made it possible to add projects through Google Drive or paste a YouTube link and have the app understand its contents. I also split sources into deep sources and general sources so they could have different levels of importance.
Within a project, GPT is fairly good at carrying memory and context across different chat histories.
Claude, however, forgets surprisingly much when the token limit forces you to open a new chat within the same project. You have to create a handoff file and pass it along. That problem led me to design the deep-source feature.
Then I added notes and a prompt library.
I designed the prompt library so I could save prompts I used often and easily call them into a chat, like using skills in Claude or GPT.
I excitedly kept typing the features I wanted into my phone and building them.
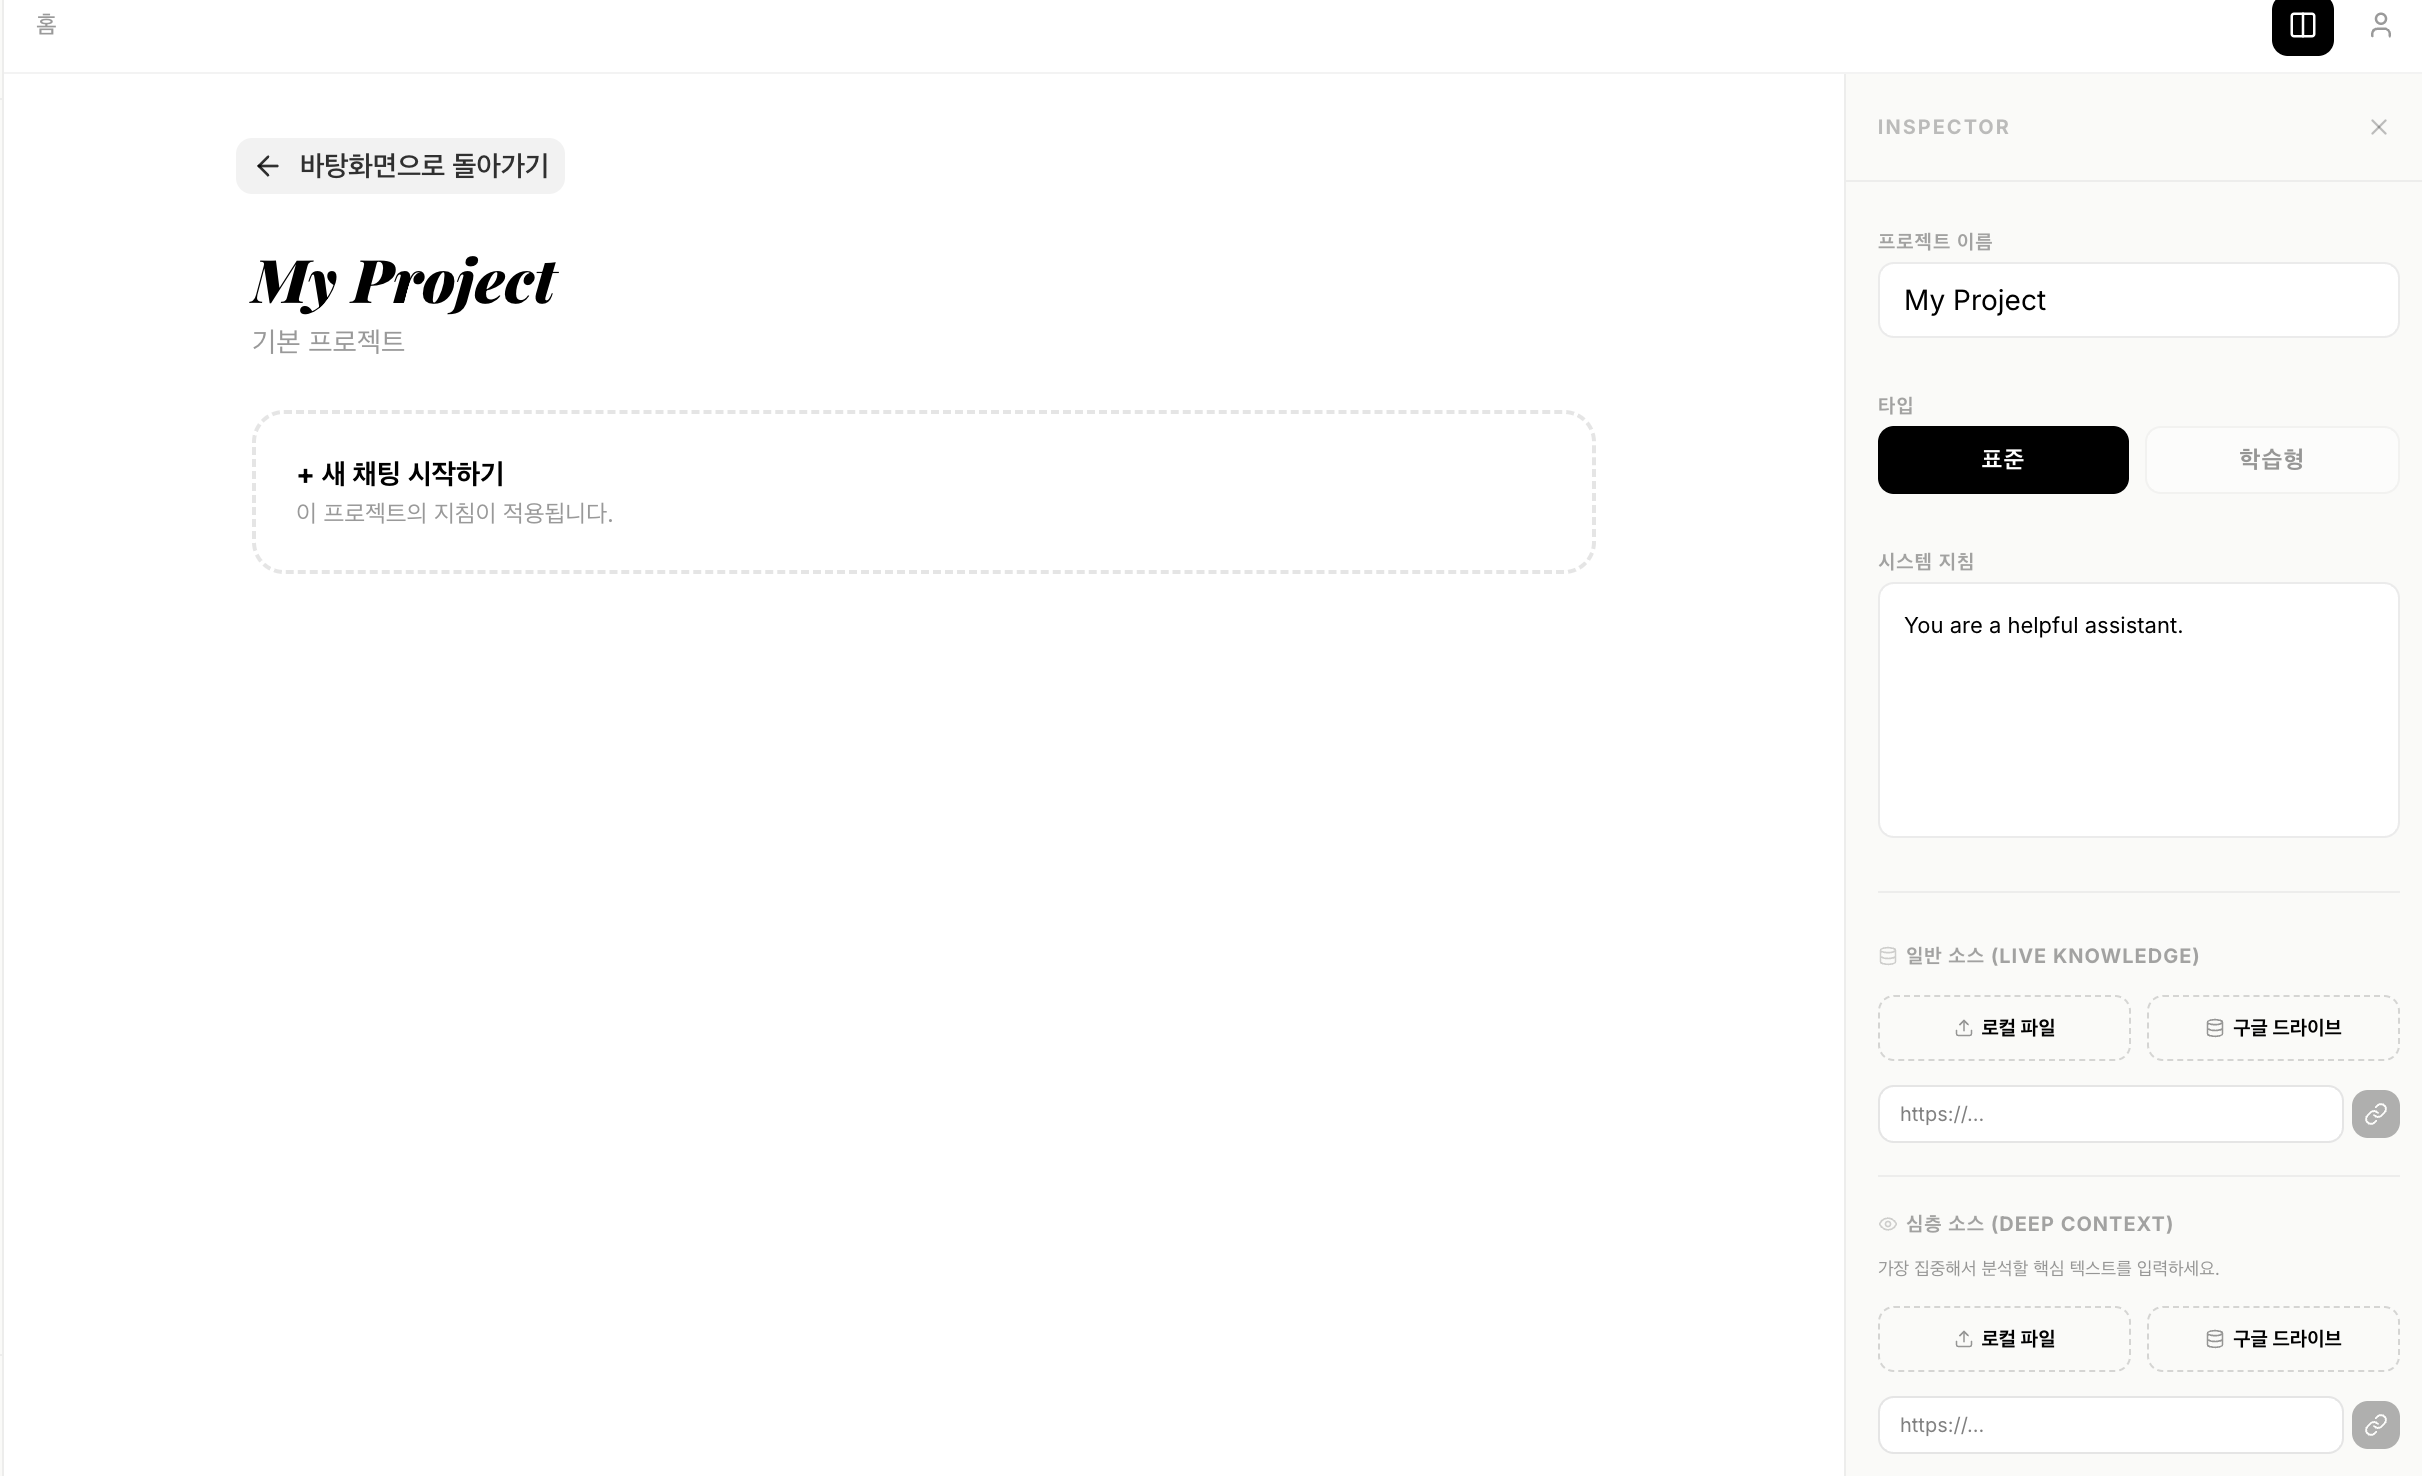
<Image 2-2. Project screen>
(Continued in Episode 3)